AI products and agents, Open source
AI Legal Document Analyzer
Structured data and semantic search for legal documents
A NestJS service that turns legal PDFs and HTML into structured metadata and vector embeddings, queryable over REST and GraphQL.
Stack
- NestJS
- TypeScript
- LangChain
- OpenAI
- Milvus
- GraphQL
- Redis
- Status
- Open source
- Type
- AI products and agents
- Source
- GitHub
The problem
Legal documents arrive as long PDFs and HTML pages, and the data inside them is hard to query.
What it does
The service ingests legal PDF and HTML files, extracts structured metadata with OpenAI and LangChain, stores semantic vectors in Milvus, and exposes REST and GraphQL APIs for querying the processed documents.
How it's built
TypeScript on Node.js and NestJS, OpenAI through LangChain, Milvus as the vector database, Redis, and GraphQL alongside REST.
Key features
- Ingests legal documents as PDF or HTML
- Extracts structured metadata with OpenAI and LangChain
- Stores semantic vectors in Milvus
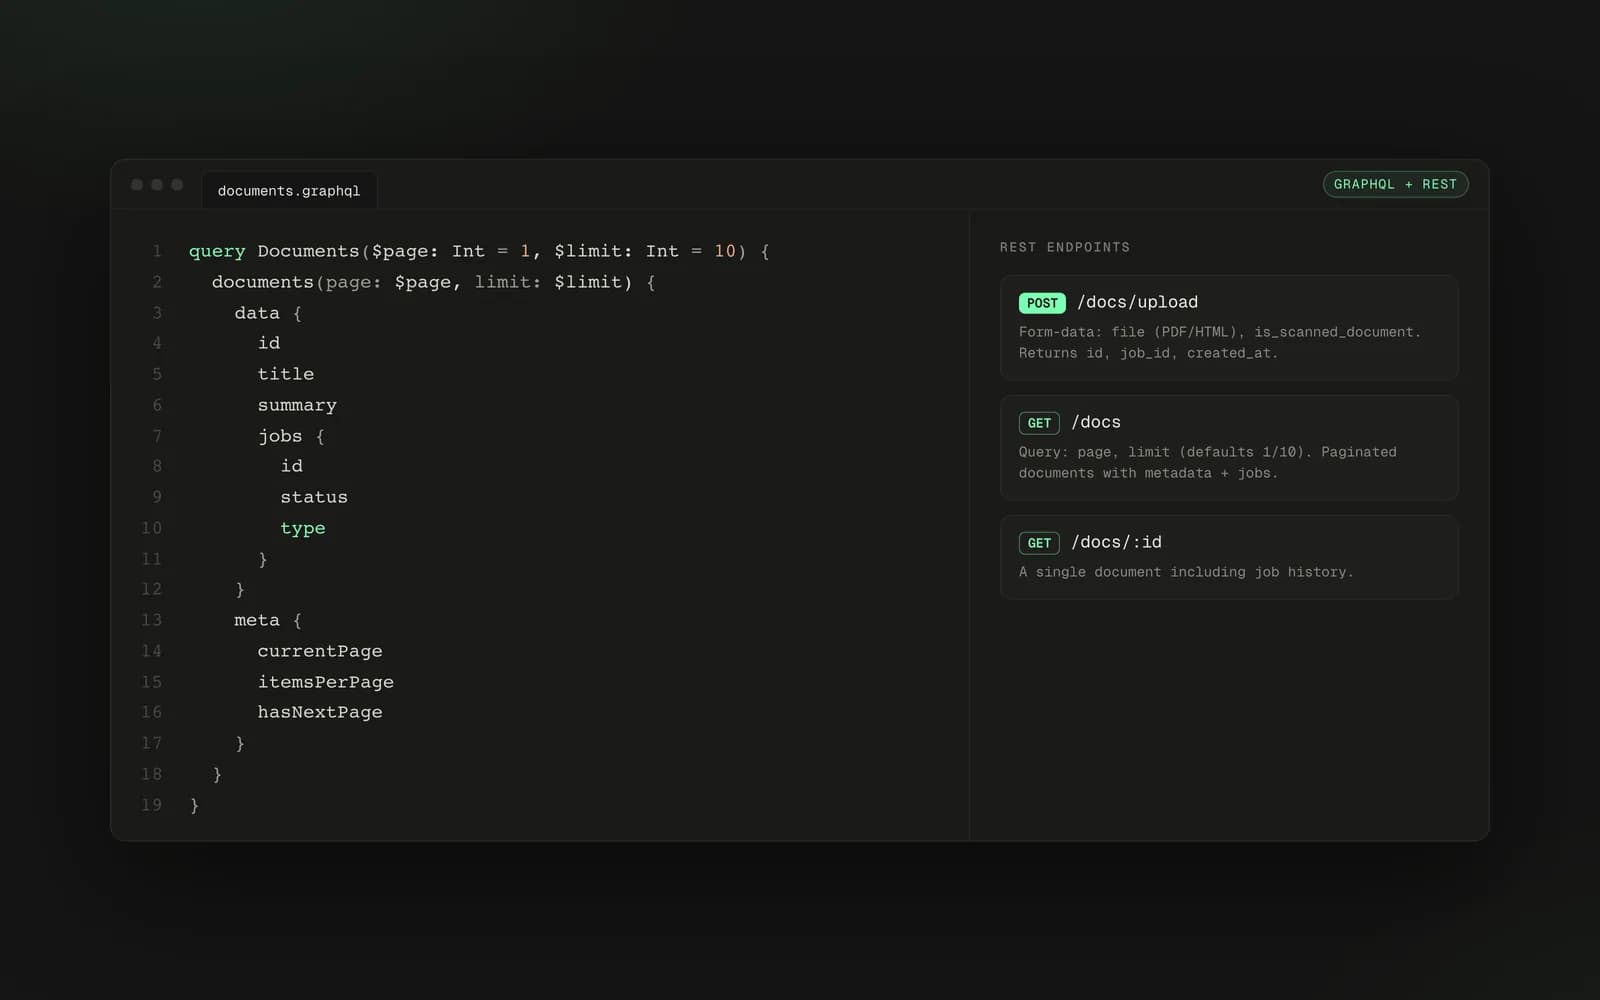
- Query processed documents over REST or GraphQL
Screens
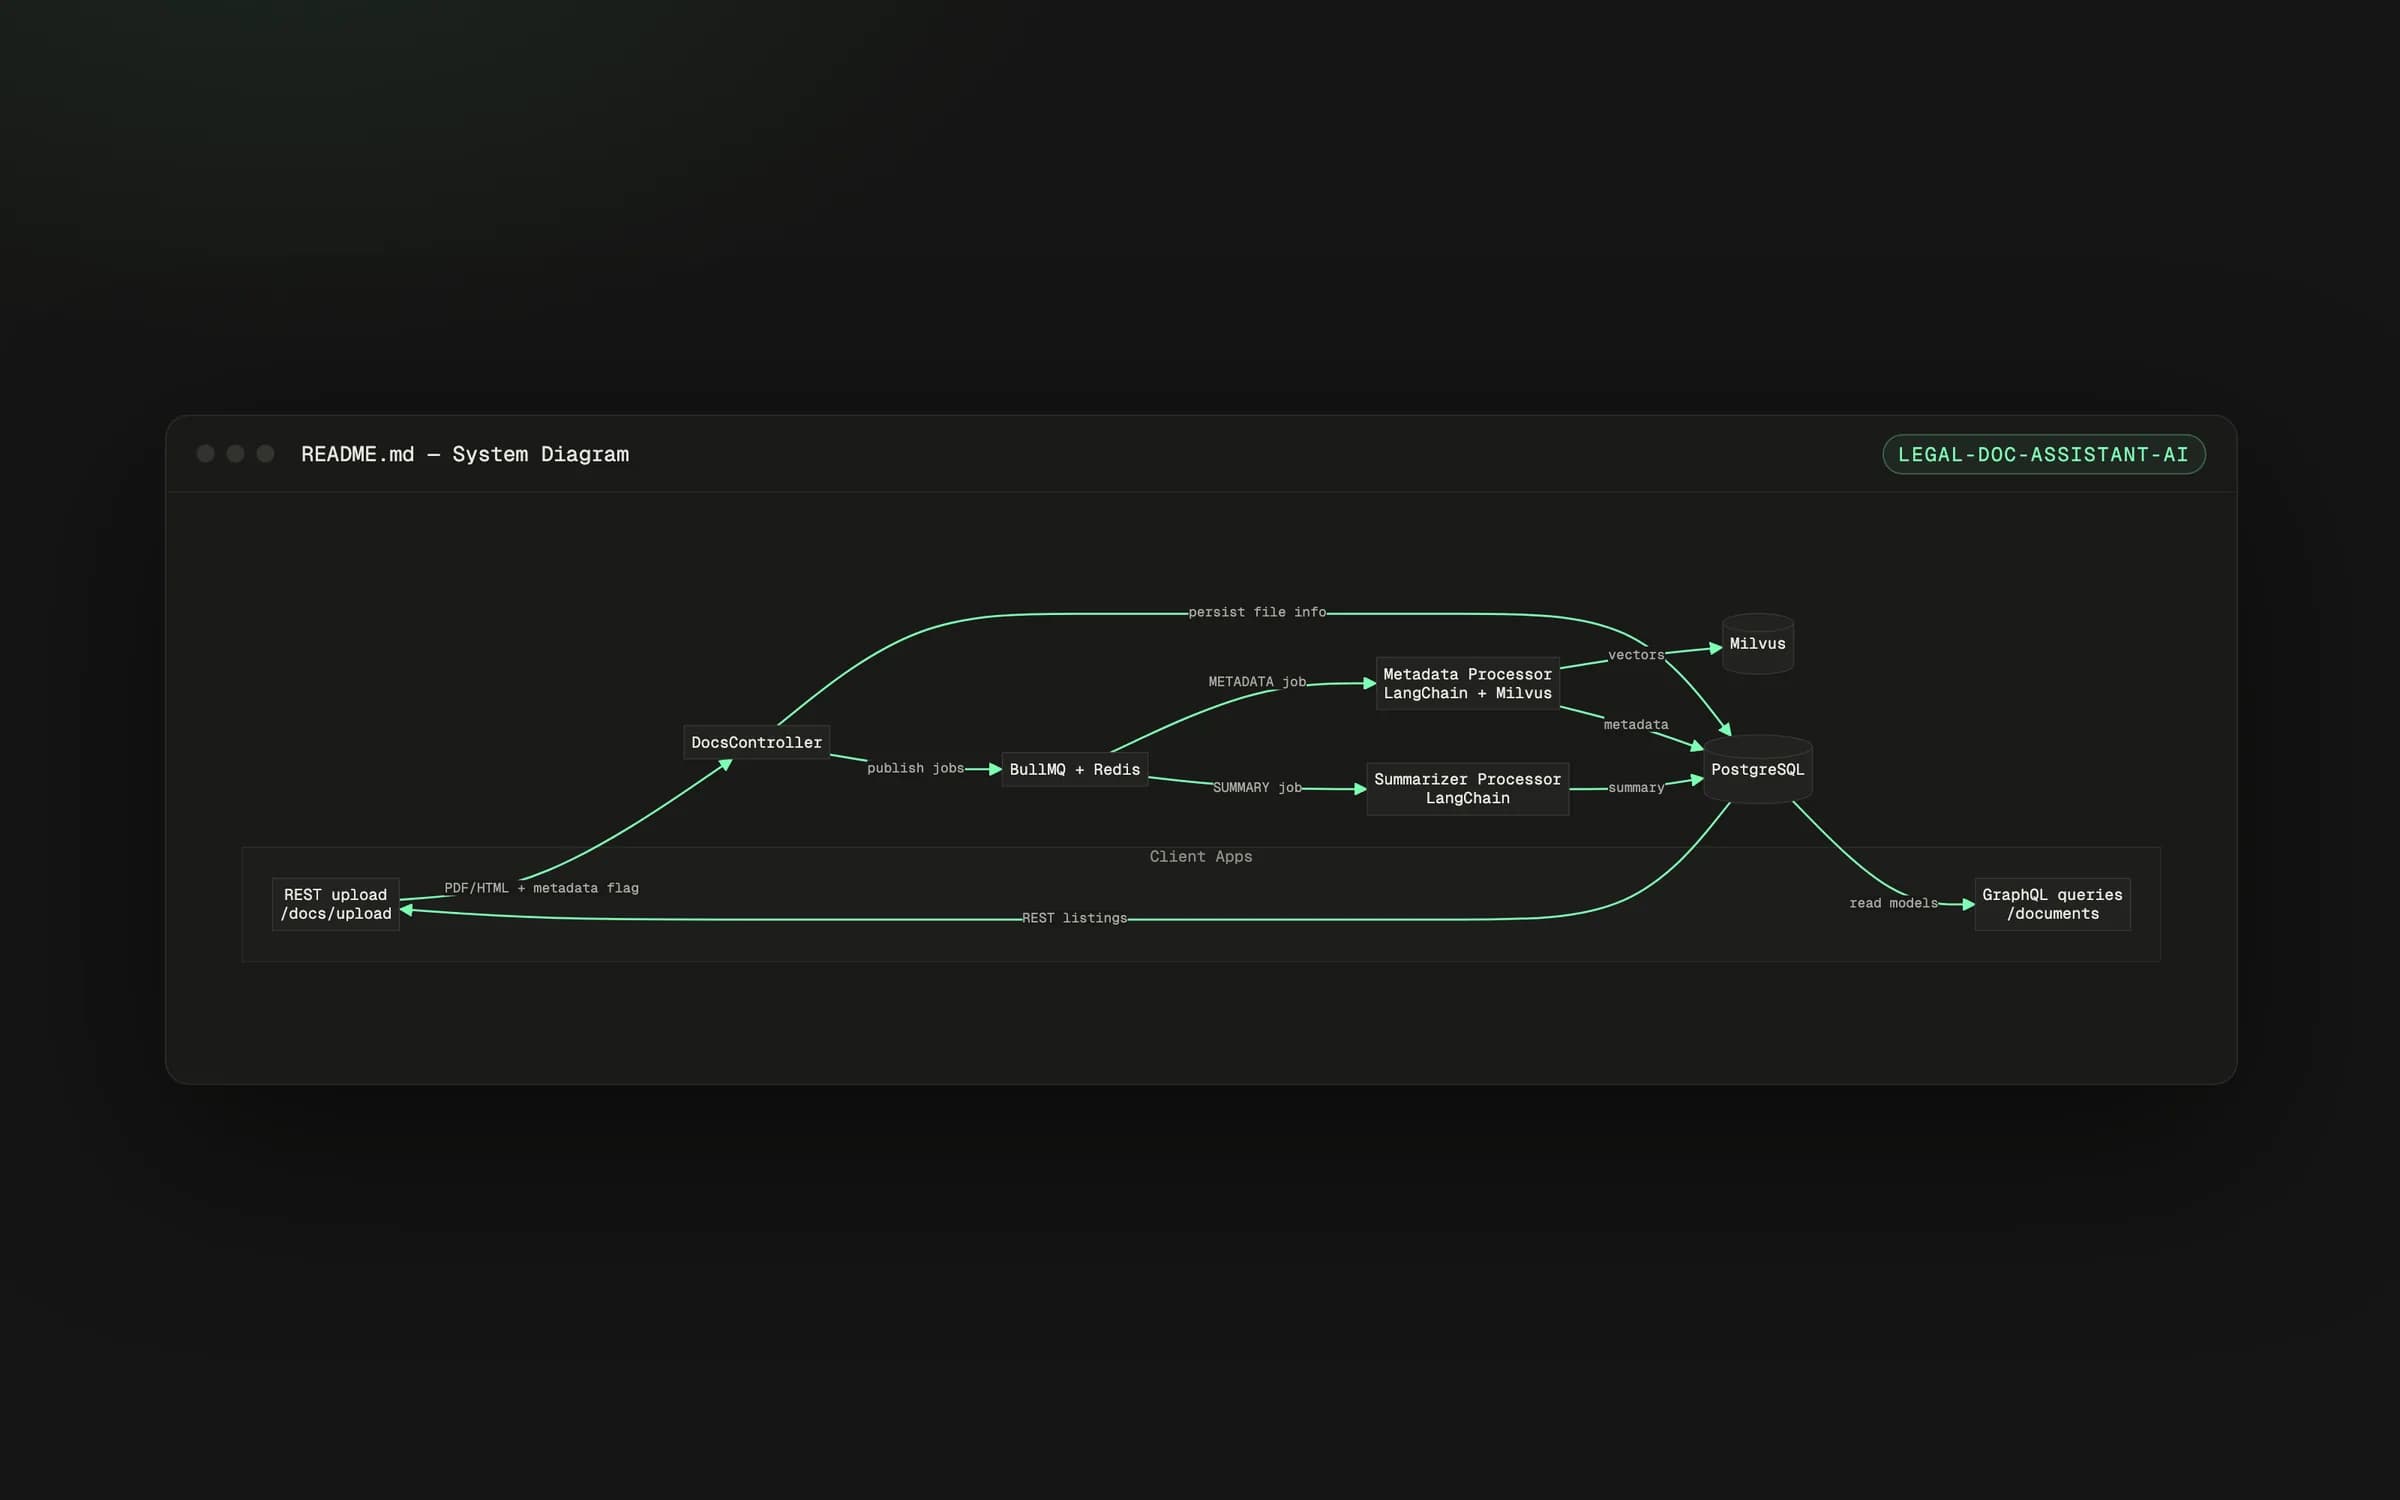
System diagram from the README
Contact
Want something like this built?